

Mistral AI launched Voxtral 3 on October 20, 2026, and the release immediately reshaped the voice AI market. The family combines speech-to-text models, an expressive text-to-speech model, and a complete voice agent SDK in one package. Because the three pieces work together, developers can now build a full voice product from a single vendor instead of stitching together separate services.
Moreover, the pricing grabs attention just as quickly as the technology. Transcription starts at only $0.0035 per minute, and the full agent pipeline starts at $0.04 per minute. Therefore, this guide explains every model in the lineup, breaks down Voxtral 3 pricing honestly, and shows how the SDK performs in practice. In addition, we compare the family against ElevenLabs, so you can choose your voice stack with confidence.
Inside the Voxtral 3 Family: Four Models, One Stack
The family covers every stage of a spoken conversation. Voxtral Small Transcribe 3 handles high accuracy transcription, while Voxtral Mini Transcribe 3 focuses on cheap batch jobs at scale. Meanwhile, Voxtral Mini Transcribe Realtime 3 streams live audio for agents, and Voxtral Speech 3 produces the spoken replies. Finally, the Voice Agent SDK ties all of these models into one streaming pipeline, so a caller can speak, hear an answer, and finish a task in a single call. In its official announcement, Mistral positions the family as a complete stack rather than a loose set of APIs.
| Model | Role | Price |
|---|---|---|
| Voxtral Mini Transcribe 3 | Batch speech-to-text, 4B parameters | $0.0035 per minute |
| Voxtral Small Transcribe 3 | High accuracy speech-to-text | $0.004 per minute |
| Voxtral Mini Transcribe Realtime 3 | Streaming speech-to-text for agents | $0.008 per minute |
| Voxtral Speech 3 (Mini TTS 3) | Text-to-speech | $13 per 1M characters |
| Voice agent pipeline with Mistral Small 4 | Listen, reason, speak | $0.04 per minute |
| Voice agent pipeline with another reasoning model | Listen, reason, speak | $0.08 per minute |
Each model also stands on its own. Consequently, a media team can buy only transcription, while a contact center can buy the whole agent pipeline.

Transcription That Understands Real Conversations
Voxtral Small Transcribe 3 supports 50 languages, including all 24 official EU languages, and it adds speaker diarization, context biasing, and end-of-turn detection. For example, context biasing lets you pass product names or staff names to the model, so specialist vocabulary lands correctly in the transcript. As a result, call recordings and meeting notes come out cleaner, with far less manual fixing afterwards.
The accuracy numbers also stand out. On the Artificial Analysis leaderboard, the Small model records a 2.1% average accent word error rate, and only two rivals rank higher. On Mistral’s own FLEURS 45 test, it posts a 4.0% word error rate with inferred language, ahead of Scribe v2 at 4.9% and Gemini 3.5 Transcribe at 4.5%, while Whisper large-v3 trails at 14.9%, as MarkTechPost reported. However, Mistral published those comparisons itself, so independent testers still need to confirm them. Even so, the early signals look strong, especially for multilingual audio, and Voxtral 3 clearly targets production workloads rather than demos.
Voxtral Speech 3 Gives Agents a Natural Voice
Listening is only half of a conversation, so Mistral built Voxtral Speech 3 for the speaking half. The model covers more than 35 languages and over 50 dialects, and it adjusts emotion, pacing, and emphasis to match the conversation. Similarly, a Pro Voice feature adapts a speaker’s voice and style across languages from about 30 minutes of reference audio. Consequently, a brand can sound consistent in Paris, Berlin, and Madrid without recording new studio sessions.
Speed matters here as well. The model starts audio in roughly 90 milliseconds, so replies feel instant rather than robotic. In addition, developers control emotion, pacing, and emphasis directly through the API, which keeps delivery consistent across thousands of calls. Therefore, the same agent can sound calm with an angry caller and upbeat with a happy one.
Voxtral 3 Pricing: What Each Minute Really Costs
Voxtral 3 pricing follows a simple per minute or per character logic. Batch transcription with Voxtral Mini Transcribe 3 costs $0.0035 per minute, the Small model costs $0.004 per minute, and the realtime model costs $0.008 per minute. For instance, a support team that transcribes 10,000 minutes of calls each month pays about $35 with the Mini batch model. In contrast, speech output costs $13 per million characters, which undercuts the older Voxtral TTS price of $16 per million characters.
The full agent pipeline costs more because it bundles every stage. With Mistral Small 4 handling the reasoning, the pipeline costs $0.04 per minute, and it rises to $0.08 per minute with a larger reasoning model. Therefore, a one hour support call handled end to end costs roughly $2.40 at the entry tier, before telephony charges. Moreover, public pricing makes forecasting easy, because finance teams can model costs per call minute instead of guessing.

How the Voxtral 3 Voice Agent SDK Works
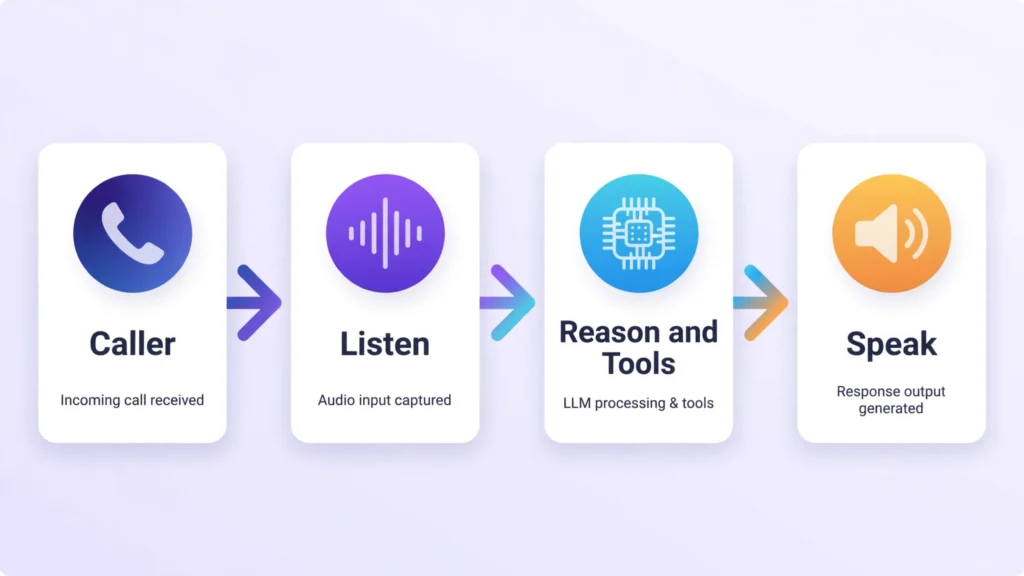
The Voxtral 3 voice agent SDK runs on LiveKit, the open source real time communication platform, and it streams speech in, reasoning, and speech out as one pipeline. Firstly, Voxtral Mini Transcribe Realtime 3 listens and detects the moment the caller finishes speaking. Next, a reasoning model such as Mistral Small 4 thinks through the request and calls tools when needed. Then Voxtral Speech 3 answers in the tone of the conversation so far.
Because no stage waits for the previous one to finish, each turn completes in under one second, and the agent stops talking the moment the caller cuts in. During a live call, the agent can verify a caller’s identity, check a bill, or book an appointment through function calling, web search, and retrieval over your own systems. Moreover, Voxtral 3 answers and places calls over SIP telephony and runs in browsers and apps over WebRTC, so it connects to the contact center software you already use.
Cloud API or a Self-Hosted Voice Agent: You Choose
Deployment flexibility is a core part of the pitch. Teams can call the models through Mistral’s EU-hosted API, or through US and global endpoints, and they can test everything in the Studio playgrounds first. On the other hand, regulated industries often need audio to stay inside their own walls. For those teams, a self-hosted voice agent deployment keeps data under direct control, and Mistral arranges on-premises or private cloud setups for the full stack.
This choice also affects retention policies. Because you control the infrastructure, you decide whether conversations are stored, for how long, and where. As a result, compliance teams in healthcare and finance get a clearer path to approval than a closed, cloud only service usually offers. In addition, each pipeline stage is a separate model, so you can swap the language model, the voice, or the language without rewriting the agent.
Voxtral 3 vs ElevenLabs: Which Voice Stack Wins?
The Voxtral 3 vs ElevenLabs debate comes down to bundle versus breadth. ElevenLabs still leads on raw language coverage, since Scribe v2 handles more than 90 languages for transcription, and its voice library runs deep. In contrast, Mistral wins on packaging: one SDK, one bill, and one vendor for listening, reasoning, and speaking.
| Feature | Voxtral 3 | ElevenLabs |
|---|---|---|
| Transcription accuracy, AA-WER (Artificial Analysis) | 2.1% (Small Transcribe 3) | 2.2% (Scribe v2) |
| Transcription entry price | $0.0035 per minute | About $0.0037 per minute ($0.22 per hour list price) |
| Text-to-speech price | $13 per 1M characters | Plan based; Mistral claims its rate undercuts ElevenLabs Flash |
| Voice agent offer | Full SDK on LiveKit from $0.04 per minute | Separate agents platform |
| Deployment | API or self-hosted | Cloud API |
Price tells a similar story. On the Artificial Analysis comparison, Scribe v2 costs $3.67 per 1,000 minutes while the Small model costs $4.00, so ElevenLabs edges the pure transcription rate. However, once you add reasoning and speech for a full agent, the bundled $0.04 per minute Voxtral 3 pipeline becomes hard to beat.
Who Should Build on Voxtral 3?
Several types of teams gain the most from this release:
- Contact centers that want agents to resolve routine calls, such as bookings and bill checks, without hold music.
- Service desks that handle callers in many languages and need accurate transcripts for every ticket.
- Product teams building hands-free copilots for drivers, technicians, and field workers.
- European companies that must keep voice data inside the EU or inside their own data centers.
Because the entry price is low, even small teams can pilot an agent on real calls within a week. If your team already compares AI platforms before buying, our Perplexity vs Claude guide shows how we test competing tools head to head.
Frequently Asked Questions
What is Voxtral 3?
It is a family of speech models from Mistral AI, launched on October 20, 2026. It combines transcription models, the Voxtral Speech 3 text-to-speech model, and a voice agent SDK built on LiveKit.
How much does Voxtral 3 cost?
Voxtral 3 pricing starts at $0.0035 per minute for batch transcription and $0.004 per minute for the Small model. Speech costs $13 per million characters, and the full agent pipeline starts at $0.04 per minute.
What is Voxtral Mini Transcribe 3 best for?
It suits high volume batch transcription, such as call archives and media libraries. The 4B parameter model also supports diarization and context biasing, so transcripts stay structured and accurate.
How does the Voxtral 3 voice agent SDK work?
It listens with the realtime transcription model, reasons and calls tools with a model like Mistral Small 4, and replies with Voxtral Speech 3. All three stages stream together on LiveKit, so each turn finishes in under one second.
Can I run a self-hosted voice agent with this stack?
Yes. Mistral offers the full stack on your own infrastructure or in a private cloud, alongside its EU-hosted API, so you keep control over audio processing and retention.
Voxtral 3 vs ElevenLabs: which is cheaper?
For pure transcription, ElevenLabs Scribe v2 is slightly cheaper per 1,000 minutes on the Artificial Analysis listing. For a complete agent, however, the bundled $0.04 per minute pipeline usually wins.
How many languages does Voxtral Speech 3 support?
It supports more than 35 languages and over 50 dialects. Voice presets are available in 18 languages, and the model adapts emotion and pacing to the conversation.
Does Voxtral Speech 3 support voice cloning?
Yes. The Pro Voice feature adapts a speaker’s character, emotional range, and style across languages from about 30 minutes of recordings.
How accurate is the Small transcription model?
It records a 2.1% average accent word error rate on Artificial Analysis. On Mistral’s FLEURS 45 test, it posts a 4.0% word error rate with inferred language, ahead of Whisper large-v3 at 14.9%.
Conclusion
Voxtral 3 turns voice from a collection of separate APIs into one coherent stack. Mistral pairs accurate transcription, expressive speech, and a LiveKit based agent SDK, and it prices the bundle aggressively from the first minute. Meanwhile, rivals keep shipping their own speed focused models, as our Mercury 3 coverage showed earlier this month.
For businesses, the decision now depends on deployment and breadth rather than raw capability. If you need EU data control or a self-hosted option, this family deserves a pilot. If you need the widest language coverage today, ElevenLabs still holds an edge. Either way, voice agents just became cheaper to build, and that shift benefits every team that answers a phone.