
Claude Haiku 5.5 is Anthropic’s newest small model, launched on October 7, 2026, and it is now the default Haiku model on the Anthropic API. Its knowledge cutoff is June 2026. It is already trending for one reason: it promises frontier level speed for high volume work at a fraction of the usual cost. But Claude Haiku 5.5 pricing has a twist you need to understand before you switch.
I spent time comparing official pricing pages, vendor benchmarks, and independent cost analyses. This is not a hype post. This is a practical look at where Claude Haiku 5.5 wins, where it loses, and how to use it without getting surprised by the bill.
Why Claude Haiku 5.5 Is Trending Right Now
Small models are having a moment. Teams are tired of paying flagship prices for summaries, classifications, and subagent lookups. Claude Haiku 5.5 arrives at exactly \$0.10 per million input tokens and \$0.50 per million output tokens for most requests, which matches OpenAI’s cheapest tier head on. Coverage like DataNorth breakdown of the Haiku 5.5 launch shows why developers noticed immediately.
It also brings a 1M token context window, up from 200K on Haiku 4.5, plus image input and a new effort setting. That combination is rare at this price. If you liked our Perplexity vs Claude guide for picking the right tool per task, you will like this approach too. Use the small model for volume, the big model for depth.
Claude Haiku 5.5: 30 Second Overview
| What you care about | Claude Haiku 5.5 | Verdict |
|---|---|---|
| Price for short prompts | \$0.10 in, \$0.50 out per 1M | Excellent, 20x cheaper than Sonnet 5.5 |
| Price for long prompts | \$0.50 in, \$2.50 out per 1M over 100K | Good, watch the 100K cliff |
| Context window | 1M tokens | Excellent for a small model |
| Computer use | 72.4% on OSWorld 2.1 | Strong, 4x better than Haiku 4.5 |
| Terminal coding | 39.2% on Terminal Bench 4.0 | Good, still behind Sonnet 5.5 |
| Best for | Summaries, subagents, support | Perfect for high volume |
What Is Claude Haiku 5.5
Claude Haiku 5.5 is the smallest model in Anthropic’s Claude 5.5 family. It is built for jobs you run thousands of times a day. Think ticket classification, document summaries, extraction, and subagent lookups inside bigger agent workflows.
It reads text and images, handles up to 1M tokens of input (5x Haiku 4.5’s 200K), and can write up to 128K tokens per answer. It is also the first Haiku with an effort setting, with adaptive thinking on by default. Medium balances speed and quality for most teams.
We covered the broader Muse assistant in our Muse AI breakdown, and the lesson applies here too. Match the model to the task. Do not pay Opus prices for Haiku jobs.
Claude Haiku 5.5 Pricing Explained
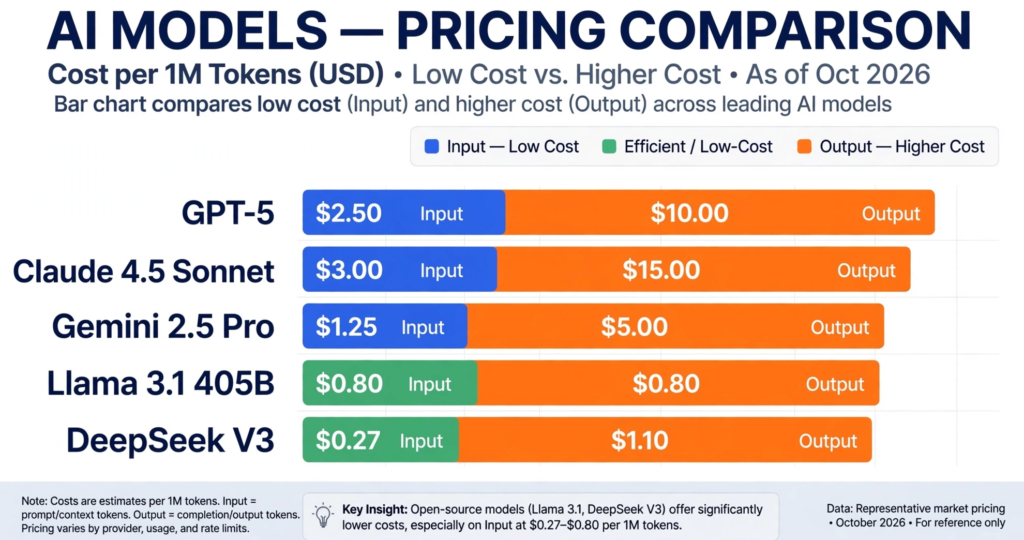
Pricing is where Claude Haiku 5.5 gets interesting. There are two tiers, not one. Prompts of 100K tokens or less cost $0.10 input and $0.50 output per million tokens. Cross 100K tokens and the entire request reprices at the higher tier, $0.50 input and $2.50 output per million tokens. Not just the overflow. The whole request.
| Prompt length | Input per 1M | Output per 1M | Cache read per 1M |
|---|---|---|---|
| Up to 100K tokens | \$0.10 | \$0.50 | \$0.01 |
| Over 100K tokens | \$0.50 | \$2.50 | \$0.05 |
| Sonnet 5.5 for reference | \$2.00 | \$10.00 | \$0.10 |
| Opus 5.5 for reference | \$4.00 | \$20.00 | \$0.20 |
The 100K price cliff is the catch: cross 100K tokens and your entire request reprices at $0.50 input / $2.50 output per million tokens — not just the overflow. A very long prompt (say, 400K tokens) can cost more on Haiku 5.5 than it did on Haiku 4.5’s flat $1/$5 pricing. Practical tip: chunk long documents into pieces under 100K tokens to stay on the $0.10/$0.50 tier.
For short prompts, Haiku 5.5 is 20x cheaper than Sonnet 5.5 and 40x cheaper than Opus 5.5 on every token class. That is why headlines say 90 percent cheaper than Haiku 4.5. But Haiku 5.5’s new tokenizer turns the same text into about 30 percent more tokens than 4.5, so real-world savings land closer to 75 to 87 percent, not the headline 90. Anthropic’s own blended claim is “around 75% less to run,” as noted in TechRepublic coverage of Haiku 5.5 pricing.
Watch the 100K cliff. A 99K prompt costs about a cent to send. At 101K, it costs about five cents. If you plan to use the full 1M window, budget for the higher tier. Prompt caching and batch processing can still cut a lot, up to 90 percent and 50 percent respectively.
Claude Haiku 5.5 Benchmarks vs Rivals
All scores below are vendor reported from Anthropic’s launch, except where noted. Treat them as directional.
| Benchmark | Claude Haiku 5.5 | Haiku 4.5 | GPT-6 Luna | Sonnet 5.5 |
|---|---|---|---|---|
| OSWorld 2.1 computer use | 72.4% | 15.7% | 48.9% | 83.9% |
| Terminal Bench 4.0 | 39.2% | 0.0% | 16.4% | 70.6% |
| GDPval office work | 1620 | 735 | 1437 | 1840 |
| Intelligence Index | 43 | Not listed | 38 | Not listed here |
The jump over Haiku 4.5 is massive. Computer use went from 15.7 percent to 72.4 percent. Terminal coding went from zero to 39.2 percent. Against GPT-6 Luna at the same \$0.10 and \$0.50 price, Haiku 5.5 leads on every shared test in Anthropic’s table.
The caveat is token usage. Independent analysis found Haiku 5.5 uses more than three times the output tokens per task than Luna in some runs. At identical per token prices, cost per finished task was higher for Haiku despite the tie on paper. Always measure cost per task, not cost per token.
Best Use Cases for Claude Haiku 5.5
- Subagent lookups: Route narrow, verifiable work to Haiku. Summaries, extraction, and one shot fixes with tests are ideal.
- Support triage: Classify tickets, draft first replies, and pull help docs. High volume, low risk.
- Computer use at scale: The OSWorld gain makes it viable for desktop automation where Haiku 4.5 failed.
- CI checks: Use it as a fast verification step before expensive models run.
A practical pattern from practical guide to cutting coding costs with Haiku 5.5 is simple. Keep Sonnet 5.5 as your default coder, route subagent work to Haiku 5.5, and watch the 100K cliff. Teams report real savings when they enforce that split.
Where Claude Haiku 5.5 Falls Short
It is not a Sonnet replacement. On Terminal Bench 4.0, Sonnet 5.5 scores 70.6 percent vs 39.2 percent for Haiku 5.5. For complex refactors, novel architecture, or multi file reasoning, Sonnet and Opus still win. And if Opus is the model you are weighing for that harder work, see how it stacks up against Meta’s frontier entry in our Muse Wonder vs Claude Opus 5.5 comparison.
It also eats tokens fast. The speed is real, nearly twice as fast in some tests, but total time per task can be longer because it generates more tokens. If your prompts are messy, the small model will do more work to get there.
Frequently Asked Questions About Claude Haiku 5.5
When was Claude Haiku 5.5 released?
Claude Haiku 5.5 was released on October 7, 2026, completing the Claude 5.5 family alongside Sonnet 5.5 and Opus 5.5.
How much does Claude Haiku 5.5 cost?
Claude Haiku 5.5 costs \$0.10 per million input tokens and \$0.50 per million output tokens for prompts up to 100K tokens. Over 100K, it rises to \$0.50 and \$2.50.
Is Claude Haiku 5.5 better than GPT-6 Luna?
On Anthropic’s published benchmarks, Claude Haiku 5.5 scores higher than GPT-6 Luna on every shared test, at the same list price. Independent cost per task tests are more mixed due to token usage.
What is the context window for Claude Haiku 5.5?
Claude Haiku 5.5 has a 1M token context window, up from 200K on Haiku 4.5, with up to 128K tokens of output per answer.
Should I use Claude Haiku 5.5 or Sonnet 5.5 for coding?
Use Claude Haiku 5.5 for fast subagent work and routine fixes. Use Sonnet 5.5 for complex coding agents where accuracy matters more than price.
Does Claude Haiku 5.5 support images?
Yes, Claude Haiku 5.5 reads text and images, which helps for computer use and document workflows.
What is the effort setting in Claude Haiku 5.5?
It is a new dial for how long the model thinks before answering. Default is medium. Higher effort helps on harder tasks but uses more tokens.
Is Claude Haiku 5.5 good for small business?
Yes, if you have high volume repetitive work like support triage or summaries. Start with short prompts under 100K to stay on the cheapest tier.
Conclusion: Should You Use Claude Haiku 5.5
Claude Haiku 5.5 is the best small model Anthropic has shipped. It is dramatically cheaper than Haiku 4.5 for typical work, far more capable on computer and terminal tasks, and priced to compete directly with GPT-6 Luna.
My take is simple. If you run volume, adopt it this week for subagent work and measure cost per finished task. If you do deep reasoning or complex builds, keep Sonnet 5.5 or Opus 5.5 as your default and let Haiku handle the busywork. That split is where the real savings live.

[…] that is the thread that unravels the 94% headline. We saw the same per-token vs per-task trap in Claude Haiku 5.5’s two-tier pricing: the sticker rate is never the whole […]
[…] applied this same cost per finished task lens in our Claude Haiku 5.5 pricing breakdown, and it exposed savings that list prices hid. The pattern repeats here. A team shipping twenty ad […]
[…] Read more: Claude Haiku 5.5: Honest Pricing and Benchmarks 2026 […]
[…] weighing that API spend, the smallest model in the family is the natural starting point, and our Claude Haiku 5.5 pricing and benchmarks breakdown shows what it costs per million tokens and where it still performs […]