
NVIDIA Nemotron 3.5 is NVIDIA’s newest open model family, and it changes the math for businesses that want AI agents without sending client data to the cloud. Specifically, the company released two models on October 15, 2026, and a third arrives on October 23. First, Super VL 120B-A12B, a 120-billion-parameter multimodal model for always-on agents. Second, Bolt 74B-A9B 24GB, which fits 74 billion parameters into 24 GB of memory. Finally, Bolt E4B 4GB targets edge devices and conversational agents. Because all three ship with open weights under a license that permits commercial use, your team can run them on your own hardware. This guide covers what each model does, what the benchmarks really say, and which one fits your workload.

What NVIDIA Nemotron 3.5 Actually Is
NVIDIA Nemotron 3.5 extends the Nemotron open model family that NVIDIA built for agentic AI. For context, the family already includes Lightning, a 30B model from August 2026, and Ultra, a 550B model for the hardest reasoning work. In contrast, the new releases target the middle of the market: multimodal agents that read documents, follow instructions, and call tools across long workflows.
NVIDIA built Super VL with the Nemotron Coalition, an AI lab group it launched in March 2026 with members including Mistral AI, Perplexity, LangChain and Cursor. As a result, the release arrived with real ecosystem support on day one. vLLM announced day-zero support, and NVIDIA confirmed compatibility with llama.cpp, Ollama, LM Studio, Unsloth and vLLM.
The Three Models at a Glance
| Model | Parameters (active) | Max context | Hardware NVIDIA names | Availability |
|---|---|---|---|---|
| Super VL 120B-A12B | 120B (12B active) | 1M tokens | 1 DGX Spark, 1 H200, 2 H100 or 1 GB200 | October 15, 2026 |
| Bolt 74B-A9B 24GB | 74B (9B active) | 256K tokens | GeForce RTX PCs (RTX 5090 tested), DGX Spark, RTX Spark laptops | October 15, 2026 |
| Bolt E4B 4GB | Not disclosed | Not disclosed | GeForce RTX, Jetson, RTX Spark, DGX Spark | October 23, 2026 |
Super VL 120B-A12B: The Always-On Agent Model
Super VL is the flagship. It uses a mixture-of-experts architecture, so only 12 billion of its 120 billion parameters activate per token. Therefore, the compute cost per token resembles a much smaller model, while the full count stays in memory for knowledge and capability. In practice, it reads text, images, short videos and PDFs, and responds in text. NVIDIA focused its vision skills on workplace inputs: OCR, tables, charts, web pages and documents.
The standout specification is the one-million-token context window. Because of it, an agent can hold an entire contract library or months of support tickets in one session. Artificial Analysis measured roughly 630 output tokens per second on 100,000-token prompts. For deployment, the card lists a single DGX Spark, one H200, two H100s or one GB200, so this model belongs on server hardware.
Bolt 74B-A9B 24GB: Serious Power on One Workstation
The NVIDIA Nemotron 3.5 Bolt 24GB model is the most interesting release for small and mid-size businesses. It compresses the 120B parent: its experts sit at about 2 bits per parameter, down from 16 bits in the reference version. As a result, the full model fits under 24 GB of memory with a 128,000-token context. NVIDIA published a 22 GB GGUF file, plus 1.7 GB for vision, so it runs on a single workstation with a GeForce RTX 5090 or a DGX Spark.
Specifically, NVIDIA pitches Bolt for agent software on your own machine: tool calling, web browsing and terminal use. The 24 GB target matters because it unlocks what closed APIs cannot match: an agent that works on company documents without any document leaving the office. For teams bound by data residency rules, therefore, that single property may outweigh raw benchmark scores.
Bolt E4B 4GB: The Edge Model Arriving October 23
Meanwhile, Bolt E4B 4GB launches on October 23, 2026. NVIDIA designed it for fast conversational and device-based agents on GeForce RTX, Jetson and RTX/DGX Spark systems. In other words, it targets voice assistants and embedded interfaces rather than heavy document reasoning. Consequently, a company could standardize on the NVIDIA Nemotron 3.5 family across its entire stack: Super VL for the server, Bolt 24GB for the workstation, and E4B for the device.
NVIDIA Nemotron 3.5 Super VL Benchmarks, Read Carefully
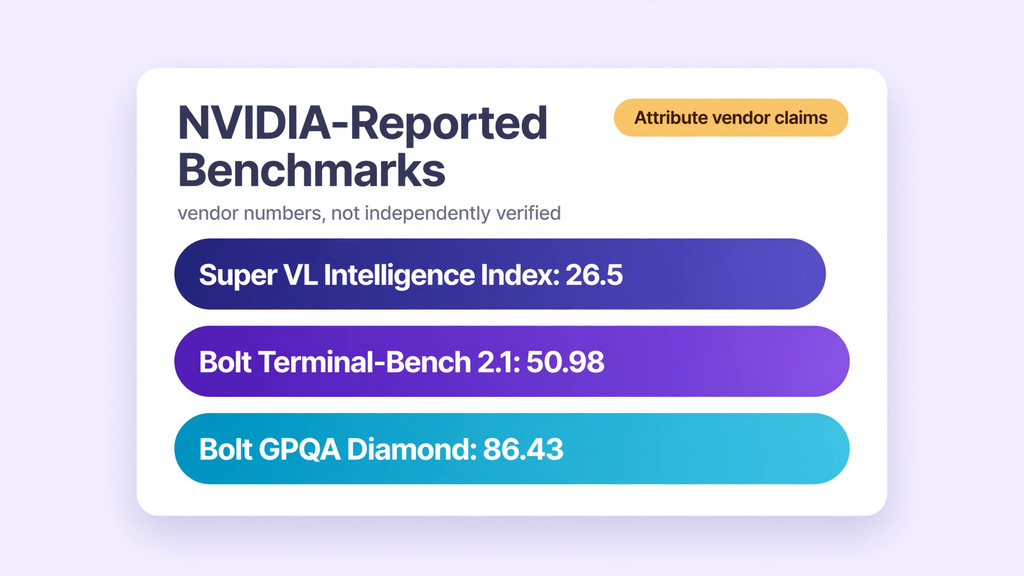
The NVIDIA Nemotron 3.5 Super VL benchmarks look strong, but every headline number below comes from NVIDIA or its partners, so treat them as claims to verify. For example, Artificial Analysis scored Super VL at 26.5 on its Intelligence Index, making it the leading US open-weight model. In addition, it doubled its predecessor’s score from 13 to 26 in seven months, while the reported cost per index task fell from $1.64 to $0.25.
NVIDIA also claims up to 5x the throughput of comparable open models on agent tasks, and comparable accuracy to its largest reasoning model at one-fifth the parameters. However, The Decoder notes that Super VL still trails the leading closed models by a wide margin, and the Artificial Analysis write-up gives the independent side of the story. Bolt’s card lists 50.98 on Terminal-Bench 2.1, 86.43 on GPQA Diamond, and 66.75 on BrowseComp against 48.74 for Qwen3.6. On the other hand, Bolt scores only 61.27 on AA-Omniscience, a non-hallucination test, versus 65.85 for Qwen3.6, which suggests the 2-bit diet costs some factuality. A detailed spec breakdown from MACCUS lays out these numbers honestly.
Which Model Fits Which Workload
Your choice comes down to hardware, data policy and task type.
| Workload | Best fit | Why |
|---|---|---|
| Document agents across contracts, PDFs and charts | Super VL | 1M-token context and native multimodal understanding |
| Local research, coding and multi-step tasks on one PC | Bolt 24GB | Fits 24 GB VRAM, no cloud round trip |
| Voice assistants and embedded interfaces | Bolt E4B | 4 GB footprint for RTX and Jetson devices |
| High-volume agent steps at scale | Lightning | 30B model with 3B active, fastest in the family |
| Hardest reasoning with maximum accuracy | Ultra | 550B flagship for the toughest problems |
In short, if your priority is data control on a budget, start with Bolt 24GB. If you need an agent that reads entire document archives in one session, Super VL is the only option in this family. Similarly, teams running Lightning for fast steps can add Super VL as the high-accuracy model without changing their stack. For teams evaluating NVIDIA Nemotron 3.5 against hosted APIs, data policy usually decides, not raw scores.

NVIDIA Nemotron 3.5 Download and Deployment Options
The NVIDIA Nemotron 3.5 download is straightforward. NVIDIA published the weights on Hugging Face and ModelScope on launch day. The models are also available as NVIDIA NIM microservices and through the major clouds, including Amazon, Google, Microsoft and Oracle.
For local deployment, the supported runtimes are llama.cpp, Ollama, LM Studio, Unsloth and vLLM, with day-zero vLLM support for Super VL. A Nemotron 3.5 Ollama install is therefore the simplest path: pull the model through Ollama’s library and point an OpenAI-compatible client at the local endpoint. As of launch week, only the older Nemotron 3.5 Lightning appeared in Ollama’s library, so verify the Bolt listing before you build around it. TechCrunch’s coverage summarizes how the enterprise and PC angles fit together.
Nemotron 3.5 for Business Agents: The Practical Payoff
The real story of Nemotron 3.5 for business agents is not any single benchmark. It is the combination of open weights, a commercial-use license, and a model at every hardware tier. Because you download the model itself, your documents never leave your infrastructure.
Early adopters point to concrete workflows. Scale AI fine-tuned Super VL for Skydance to automate vendor credit processing, and Ramp uses it to turn receipt photos into structured data. Mercor post-trained it on a few hundred tasks each for legal, software engineering and accounting work, measuring gains of 5 to 8 points in every domain. Consequently, the playbook is clear: take the open base model, post-train it on your own procedures, and deploy it where your data lives. If you are comparing hosted options instead, our Perplexity vs Claude comparison covers the API-first side of the market, while our guide to DeepSeek V4.1 Flash 1017 shows how cheap hosted agentic tasks have become.
The Honest Caveats
No release deserves blind trust. First, all headline scores come from NVIDIA’s own testing, and independent evaluations are still thin. Second, Super VL trails the leading closed models by a wide margin in overall rankings, even though it leads US open-weight models. Third, Bolt’s 2-bit compression is aggressive, and its weak AA-Omniscience score suggests the diet costs something on factuality. Finally, NVIDIA has not published managed pricing, so the true cost depends on your hardware or host. It simply means you should pilot NVIDIA Nemotron 3.5 on your own data first, and because the weights are open, that pilot costs nothing but time.
Frequently Asked Questions
What is NVIDIA Nemotron 3.5 and when was it released?
It is NVIDIA’s open model family for AI agents, launched October 15, 2026. It includes Super VL 120B-A12B for data center agents and Bolt 74B-A9B 24GB for local workstations, with Bolt E4B 4GB for edge devices following on October 23. All three ship with open weights under the OpenMDW-1.1 license, which allows commercial use.
What are the NVIDIA Nemotron 3.5 Super VL benchmarks?
Artificial Analysis scored Super VL at 26.5 on its Intelligence Index, making it the leading US open-weight model. NVIDIA claims up to 5x the throughput of comparable open models at one-fifth the parameters. However, all headline numbers come from NVIDIA, and the model still trails leading closed models overall.
How much VRAM does NVIDIA Nemotron 3.5 Bolt 24GB need?
It targets 24 GB of memory, with experts compressed to about 2 bits per parameter. The GGUF file is 22 GB plus 1.7 GB for vision. It runs on a single GeForce RTX 5090-class PC, a DGX Spark, or RTX Spark laptops with a 128,000-token context.
Where can I find the NVIDIA Nemotron 3.5 download?
NVIDIA published the weights on Hugging Face and ModelScope at launch, and OpenRouter offered a free tier on October 15. The models are also available as NVIDIA NIM microservices and on major clouds including Amazon, Google, Microsoft and Oracle.
Can I do a Nemotron 3.5 Ollama install?
Yes. NVIDIA lists Ollama among the supported runtimes alongside llama.cpp, LM Studio, Unsloth and vLLM. As of launch week, only the older Nemotron 3.5 Lightning appeared in Ollama’s library, so verify the Bolt listing first.
What is the Nemotron 3.5 Bolt E4B release date?
NVIDIA scheduled Bolt E4B 4GB for October 23, 2026. Specifically, it targets fast conversational and device-based agents on GeForce RTX, Jetson and RTX/DGX Spark systems.
Is Nemotron 3.5 good for business agents?
The strongest argument is data control: the models run on your hardware, so sensitive documents never leave the office. Early fine-tuning results from Scale AI, Ramp and Mercor show measurable gains on legal, accounting and software tasks, and the license allows commercial use and post-training on proprietary data.
Should a small business choose Bolt or Super VL?
Most small businesses should start with Bolt 24GB. It runs on one workstation, handles research, writing and coding agents locally, and keeps data in-house. Choose Super VL only if you need million-token context or heavy multimodal document work on server hardware such as a DGX Spark or H200 GPUs.
Conclusion: Should You Act This Week
NVIDIA Nemotron 3.5 earns its attention. Super VL gives enterprises an open, multimodal agent model with million-token context, while Bolt 24GB puts serious capability on a single workstation. Because the weights are open and the license permits commercial use, the barrier to a pilot is nearly zero.
The smart move this week is a small, honest pilot. Pick one repetitive document workflow, run Bolt locally against it, and compare the output with your current process. If the numbers hold, you gain a fixed-cost agent that never sends data to the cloud. Finally, mark October 23 for the Bolt E4B launch, which completes the family from data center to edge.


[…] another specialised model built for agents, see our guide to NVIDIA Nemotron 3.5, because it shows how a multimodal model can support agent workflows that need vision as well as […]