
ElevenLabs launched Eleven Realtime on October 20, 2026, and the release changes how developers build voice agents. Instead of wiring together separate speech recognition, a language model and text to speech tools, teams now pick a single speech-to-speech voice agent model that listens, reasons and replies inside one system. The family ships in two sizes, v1 Mini and v1 Max, and both models speak more than 90 languages with access to over 17,000 voices.
The timing matters because voice agents now handle real customer work, from support calls to lead qualification. However, most teams still struggle with slow replies and clumsy turn-taking. Therefore, a model that starts answering in about half a second and knows when a caller has finished speaking solves a genuine business problem. This guide explains how the two models differ, what the benchmarks actually show, how pricing works and how the API compares with OpenAI.
What Is Eleven Realtime and Why One Model Matters
A traditional voice agent chains three separate systems together, so every handoff adds delay and another point of failure. In contrast, Eleven Realtime folds speech recognition, voice activity detection, turn-taking, reasoning and speech generation into one managed system. As a result, the model hears pauses, interruptions and backchannels directly, rather than guessing from a transcript. For example, it can tell the difference between a caller who finished a sentence and a caller who only said mm-hmm. In addition, developers keep full control over the voice, because every agent can use any voice from the ElevenLabs library.
Eleven Realtime v1 Mini vs Max: The Key Differences
The Eleven Realtime v1 Mini vs Max choice comes down to conversation flow versus task completion. Mini targets natural, everyday conversations where cost matters most, such as AI assistants, tutors and interactive characters. Meanwhile, Max targets demanding work, such as customer support, lead qualification and multi-step tool workflows. Both models share the same languages and voice library, so the decision rests on accuracy, tool use and price rather than features.

| Feature | v1 Mini | v1 Max |
|---|---|---|
| Best for | Natural conversations, assistants, tutors | Support agents, lead qualification, tool workflows |
| Big Bench Audio | 75.9% | 98.8% |
| Time to first audio | 0.62 seconds | 0.57 seconds |
| Tool task completion | 60.3% | 87.1% |
| Full-Duplex-Bench | 95.8% | 94.1% |
| Cost position | Lower per minute price | Higher per minute price |
Interestingly, Mini actually wins the conversation dynamics test, because Full-Duplex-Bench measures pauses, interruptions and backchannels. Max, on the other hand, dominates reasoning and tool use by a wide margin. Consequently, the cheaper model suits chatty, low-stakes conversations, while the flagship suits agents that must complete real tasks correctly.
Benchmark Results: Speed and Accuracy in Detail
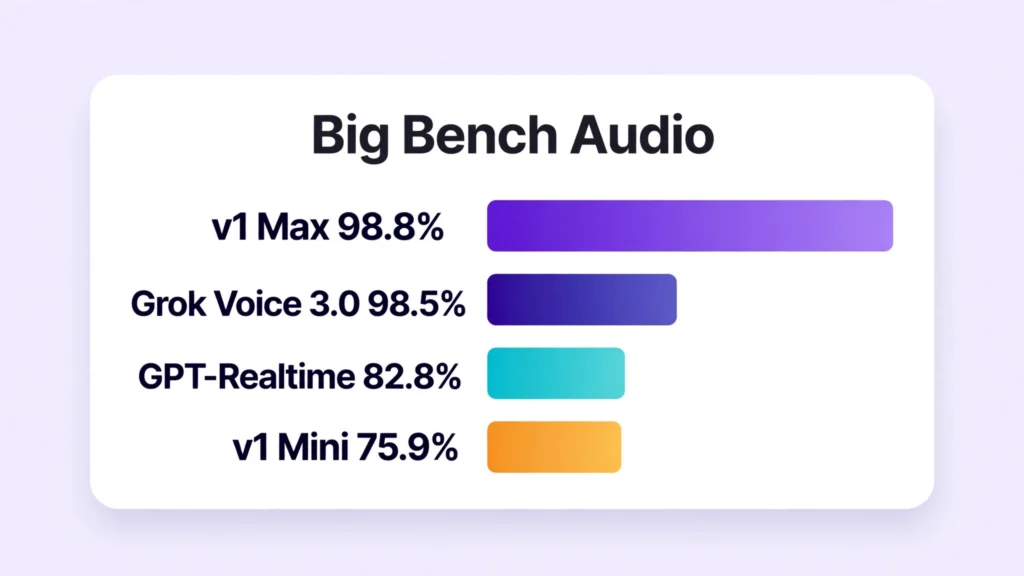
Artificial Analysis evaluated both models across three public benchmarks, and ElevenLabs published the results at launch. On Big Bench Audio, which asks 1,000 spoken reasoning questions, Max scored 98.8 percent, while Mini scored 75.9 percent. ElevenLabs reports that the Max score also edges past Grok Voice 3.0 at 98.5 percent on the same test. In addition, Max starts speaking after 0.57 seconds on average, compared with 0.62 seconds for Mini, so the flagship leads on speed and accuracy at the same time.
Speed shapes how natural an agent feels, and our Mercury 3 speed guide showed the same pattern for text models. However, readers should treat these numbers with care, because the launch figures come from the vendor and independent labs have not yet reproduced the full set. Similarly, tool task completion favors Max heavily at 87.1 percent against 60.3 percent, which matters for agents that book, check and update records during a call. Therefore, the benchmark story stays simple: Max reasons far better, Mini converses slightly more naturally, and both respond fast enough for live calls.
Eleven Realtime vs GPT-Realtime
The Eleven Realtime vs GPT-Realtime contest matters because many teams already run OpenAI’s stack. OpenAI reports that GPT-Realtime scores 82.8 percent on Big Bench Audio in its official gpt-realtime announcement, so the Max figure of 98.8 percent looks strong, although the two numbers come from different evaluation runs. Readers who compared chat assistants in our Perplexity vs Claude comparison know that headline scores rarely tell the whole story.
On the other hand, ElevenLabs removes the biggest switching cost, because its Realtime API follows the OpenAI protocol. As a result, a team can test the new models by changing the endpoint and the model name, while the OpenAI SDK keeps working unchanged. In contrast, a traditional migration would force a full rebuild of the audio pipeline. Therefore, existing OpenAI voice projects can trial Mini and Max with minimal engineering effort.
Eleven Realtime Pricing: What Teams Actually Pay
Eleven Realtime pricing follows a simple structure: you pay per minute of conversation, plus token costs for the reasoning work behind each reply. In ElevenAgents, the models follow the platform’s standard per minute pricing, and the model selector shows an estimated cost per minute before you launch an agent. Max costs more per minute than Mini, which matches its stronger reasoning and tool use scores.
Through the Eleven Realtime API, billing counts each minute of connected audio, plus tokens, and ElevenLabs had not published the exact token rate at launch. Therefore, budget-conscious teams should model both the minute rate and the token usage before they commit. For example, a high-volume support line on Mini will cost far less than the same line on Max, while a complex sales agent may earn back the Max premium through higher completion rates.
Getting Started With the Eleven Realtime API
Developers get two doors into the same models. Firstly, the ElevenAgents platform offers the fastest route, because you configure the agent, pick Mini or Max, choose a voice and deploy without managing audio infrastructure. The ElevenAgents voice agent can then answer on the phone, on the web and on WhatsApp, plus inside contact center platforms.
- Create an ElevenLabs account and open ElevenAgents or the API dashboard.
- Choose v1 Mini for natural conversations or v1 Max for tool-heavy tasks.
- Point your client at the Realtime API endpoint and set the model name; existing OpenAI code needs only those two changes.
- Test turn-taking and interruptions with real callers before you launch.

One limitation deserves attention: the API runs over WebSocket at launch, and WebRTC connections are not supported yet. The Decoder covered the launch in its Eleven Realtime launch report, which confirms both access routes. Consequently, teams that built on WebRTC should plan a small migration step. In addition, ElevenLabs says no model on the Artificial Analysis speech-to-speech leaderboard is currently both faster and more accurate than Max, a claim worth testing on your own traffic.
Which Model Fits Your Business?
Choose Mini when the conversation itself is the product, for example in tutoring apps, companion characters and simple booking assistants. Because Mini handles pauses and interruptions gracefully, callers feel heard rather than processed. Choose Max when the agent must follow multi-step instructions, call tools reliably and qualify leads or resolve support cases. Finally, consider running both models together: Mini can greet and route callers, while Max takes over when a task turns complex.
Frequently Asked Questions
What is Eleven Realtime?
It is a family of speech-to-speech models from ElevenLabs, launched on October 20, 2026. Each model combines speech recognition, turn-taking, reasoning and voice generation in one system, so developers build a complete voice agent from a single component instead of a fragile pipeline.
What is the difference between v1 Mini and v1 Max?
Mini favors natural conversation at a lower cost, while Max favors reasoning and tool use. For example, Max scores 98.8 percent on Big Bench Audio against 75.9 percent for Mini, and it completes 87.1 percent of tool tasks against 60.3 percent. However, Mini handles conversation dynamics slightly better.
How much does Eleven Realtime cost?
Pricing runs per minute of conversation, plus token costs, and Max costs more per minute than Mini. In ElevenAgents, the model selector shows an estimated cost per minute before launch. However, ElevenLabs had not published the exact API token rate at launch, so check the pricing page before you budget.
Is Eleven Realtime better than GPT-Realtime?
On Big Bench Audio, Max scores 98.8 percent, while OpenAI reports 82.8 percent for GPT-Realtime, although different teams ran those evaluations. In addition, the OpenAI-compatible API makes switching cheap. Therefore, test both models on your own calls before you decide.
How do I access the Eleven Realtime API?
You connect over WebSocket and pick the model by name. Because the API follows the OpenAI Realtime protocol, existing OpenAI code usually needs only a new endpoint and a new model name. Alternatively, you can skip code entirely and build inside ElevenAgents.
What does the ElevenAgents voice agent platform include?
It includes the agent builder, the voice library of over 17,000 voices and deployment to phone, web and WhatsApp channels. In addition, it connects with contact center platforms, so a business can launch a working agent without managing servers or audio pipelines.
What is a speech-to-speech voice agent?
A speech-to-speech voice agent listens to spoken input and replies with spoken output, without a separate text step in the middle. As a result, it reacts to tone, pauses and interruptions more naturally than older systems that chained transcription, a chatbot and a voice generator together.
Which languages and voices do the models support?
Both models support more than 90 languages, and they can use any of the over 17,000 voices in the ElevenLabs library. Therefore, a team can serve several markets with one agent setup, instead of building a separate voice for every country.
Can the models handle interruptions and pauses?
Yes, turn-taking sits inside the model itself, so the agent knows when to speak and when to stay silent. Mini scores 95.8 percent on Full-Duplex-Bench, which measures pauses, interruptions and backchannels, while Max scores 94.1 percent. Consequently, callers can interrupt naturally, just as they would with a human agent.
Conclusion: One Model Family, Two Clear Choices
Eleven Realtime simplifies voice agent development in a way the market has wanted for years. Instead of assembling a fragile pipeline, teams now choose between a natural, affordable conversationalist and a fast, accurate task completer. However, the smartest move is still to test both models on real calls, because vendor benchmarks only predict so much. Start with Mini for conversation-heavy work, try Max where tools and reasoning decide revenue, and let your own call data make the final call.